INDEPENDENT PRODUCT WORK

AI & apps.
Useful tools. Playful ideas.

Alongside my analytics work, I create apps for practical tasks and shared experiences. These independent projects show how I approach product design, data handling, testing and the decisions that shape a useful or enjoyable product.

MULTIPLAYER GAME

So Wrong

Play online

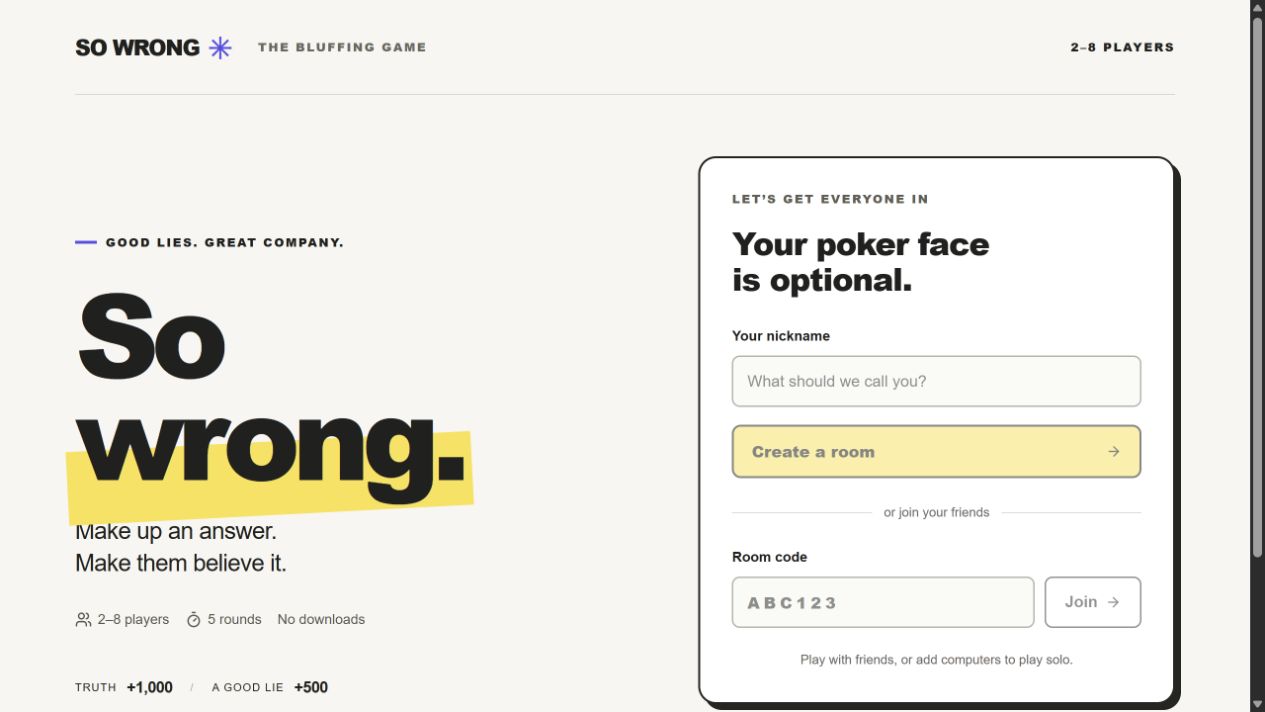
Make up an answer. Make them believe it.

A browser party game for 2–8 players: invent a believable bluff, find the truth, and earn points for fooling friends. Seven genres offer 100 questions each; pick one, mix favorites, or choose all 700.

My contribution
I created the game with AI-assisted development, shaping its rules, visual direction and genre choices through iterative playtesting. The implementation includes shared rooms, timed rounds, computer opponents and score reveals.
Design decision
The server controls scoring and hides answers until the reveal. Computer players use preset bluffs and random eligible guesses, so play requires no external AI service.
So Wrong: make up an answer, make them believe it. Create a room or join friends by code.
RECIPES & PERSONAL KNOWLEDGE

SavorShelf

In development

Keep the recipe. Remember what made it better.

A recipe app built around the way a collection changes over time: saved dishes, personal notes, ratings and named versions. The focus is making a recipe easy to find, adapt and cook again.

My contribution
I’m developing the Android and web experience, recipe import and version handling, and a companion workflow for creating and revising recipes with AI.
Design decision
A generated revision is a draft to review. It should not silently replace a saved recipe or erase the cook’s notes.
DECISION SUPPORT

Fourth & Forever

Private web app

Advice is only useful when it understands the league.

A fantasy football adviser that brings roster context, scoring and available projections into the same decision. The app compares lineup and roster options and explains the assumptions behind each result.

My contribution
I’m building the web and Android app, read-only roster integration, lineup calculations and local-model question interpretation.
Design decision
Roster freshness and projection freshness are different. Missing information stays visible, and the app does not make league transactions.
WORKFLOW AUTOMATION

Quick Apply

Private working app

Spend less time organizing applications—and more time choosing the right roles.

A phone-friendly job-search workspace for saving roles, reviewing restrictions, preparing answers and tracking responses. It connects each application to the resume and role information used at submission.

My contribution
I built job intake, duplicate checks, evidence-linked restriction flags, editable profile-based drafts and application analytics in an authenticated web app.
Design decision
Unknown requirements need review. Drafts use recorded profile facts, and submitting an application remains a deliberate action by the user.
IMPLEMENTATION NOTES

Where AI fits—and how I check its work.

These projects use AI in different ways: to help develop software, draft recipe variations, or interpret a question. I define the model’s job narrowly, then use application logic and review to decide what happens next. Using an existing model is different from training one; these are integration projects, not claims of original model research.

So Wrong: AI-assisted development, rule-based gameplayShared state, computer opponents and testing

My role and the use of AI

I directed the concept, name, features and iteration, using Codex to assist with implementation, question drafting, tests and deployment. I played the game and used that feedback to guide the next changes. AI assistance is part of the development process; no language model runs during a game.

How a round stays fair

A shared server clock advances writing, voting and reveals. The server keeps the answer bank out of the browser and calculates points: 1,000 for identifying the truth and 500 for each player fooled. Computer opponents submit preset decoys and choose eligible answers randomly without consulting the truth flag.

Checks and limits

The 700-question release passed 19 game and content tests, type checking and a production build. A public two-session check verified genre selection and two scored rounds; full five-round local checks covered shared settings and game progression. Phone-sized layouts were inspected separately. These checks are not a large-scale load test. Source links make facts reviewable; reference availability alone does not establish factual accuracy.

Privacy and replay

Players use nicknames and room codes without game accounts. Bluffs are stored on the game server to run the room; this is not browser-only processing. Rooms expire after 24 hours, and expired records are cleaned up when another room is created. Room history avoids repeated questions until the selected pool cycles.

SavorShelf: structured recipe generation and revisionInputs, validation and saved versions

What the model receives

The creator companion sends the user’s dish request and visible preferences. A revision includes the latest complete draft and the requested change. The workflow does not send the entire saved collection or an unlimited chat history.

What it produces

The requested output is a structured recipe: ingredients, quantities, servings, steps and notes. This gives the app fields it can parse and validate instead of treating a free-form answer as a finished recipe. The current provider adapter uses Puter; keeping that adapter separate allows the provider to change without moving ownership of recipe state.

How the app handles the result

The companion parses the response, validates the recipe structure and presents a draft. The user reviews it, names the version and imports it deliberately. Recipe identity and version handling protect the original card; repeated imports of the same formulation should not create duplicate recipes.

Failures and limits

An invalid response or failed request retains the last valid draft. There is no automatic retry; stopping locally ignores late results but does not guarantee a provider request has stopped. Structural validation cannot prove that a dish tastes good, a substitution behaves correctly or dietary advice is appropriate. New recipes remain untested drafts until reviewed and tried. The web creator is published; recipe enrichment and evaluation of generated recipes remain ongoing work.

Fourth & Forever: language understanding backed by calculationsConstrained output and source-aware decisions

The model’s job

A local language-model integration interprets a football question and returns an intent, such as lineup, waiver, trade or scoring, plus referenced players. It receives a bounded roster context and the two most recent questions for follow-up references. It is instructed to interpret the request, not generate advice or execute tools.

Grounding the answer

The response must match a defined JSON structure. Allowed intents are enumerated, player references must exist in the supplied roster, and duplicate or unknown references are rejected. Application code then resolves the request against the available data. Lineup and roster comparisons are calculated separately from the language model.

Why data freshness matters

A successful roster refresh does not make a captured projection current. The app preserves the distinction between connected rosters, reviewed imports and missing evidence. A recommendation needs compatible scoring, eligible lineup slots and the relevant player information; fluent model output cannot supply a missing injury report or lineup-lock status.

Failure handling and limits

The local request has a timeout and response-size limit. Invalid structure or invented player references fail validation. The integration treats supplied text as untrusted input, but prompting alone is not a security guarantee—the constrained output and code checks matter. The app remains read-only, with no automated league transactions. Broader current-data coverage and the Android update are unfinished.
Quick Apply: choosing rules where they are easier to inspectProfile-based drafts without a language model

What runs today

Quick Apply uses explicit screening rules, duplicate checks and editable templates. Restriction flags point back to evidence in the posting, and drafts draw from recorded profile facts. This is workflow automation, not a model making an eligibility decision.

The analytical decision

Rules are useful when the question is specific: whether a posting mentions office attendance, whether a requisition is already saved, or which resume was used for a submitted application. Missing requirements remain review items. An application is only recorded as submitted when the user confirms that action.

What an AI extension would need

A future model-assisted drafting feature would need a bounded set of approved profile facts, traceable support for each claim and a review step before use. It would also need evaluation against unsupported credentials, ambiguous restrictions and instructions embedded in job descriptions. That is a design requirement, not a feature claimed as implemented.

Try the public tools

Compare two reports or explore a profit scenario directly in your browser.

Open the analytics lab